90 Days to a Risk Aware AI Control Tower Pilot for Logistics Teams

An AI logistics control tower is a centralized platform that turns scattered shipment, inventory, and supplier data into prioritized, decision-ready actions. Its core benefit is speed: it shortens the gap between spotting a disruption and resolving it, which cuts the cost of delays, expedites, and manual firefighting. The defining shift in 2026 is agentic AI, which pushes towers from simply recommending a fix to actually executing one under human oversight.
TL;DR:
- Control towers require comprehensive data integration from internal and external sources to enable real-time exception detection and accurate decision analysis.
- Moving beyond recommendations, agentic AI can automate low-risk actions but demands stringent governance, audit trails, and confidence thresholds before deployment.
- A phased rollout emphasizing narrow, high-value workflows ensures measurable improvements within 60 to 90 days and mitigates organizational resistance.
- Successful pilots focus on one specific, low-risk task, such as carrier reassignments, with clear metrics to assess decision velocity, exception volume, and process speed.
- Vendors must demonstrate live data connectivity, explain autonomous decision pathways, and explicitly detail integration scope and governance controls before purchase.
Table of Contents
- Core Capabilities: Visibility, Detection, Analytics, and Action
- Overlay vs Orchestration: Choosing the Right Starting Point
- Agentic AI and Automation: Power and Guardrails
- Architecture and Data Readiness: The Unified Data Layer
- A Practical Roadmap and the KPIs That Prove Value
- A 90-Day Pilot Example and What It Delivers
- Where AI Control Towers Are Heading Next
- What Pilots Have Shown in Practice
- Where These Projects Run Into Trouble
- How to Evaluate a Control Tower Before You Buy
- Common Use Cases Across Logistics Operations
- Balancing Ambition, Risk, and Speed When Automating Decisions
- Getting From Visibility to Action in 90 Days
- Sources
- FAQ
Core Capabilities: Visibility, Detection, Analytics, and Action
A control tower earns its name by stacking several distinct capabilities, not just a dashboard. Each layer builds on the one below it, and skipping a layer is why many towers deliver visibility without ever delivering value.
End-to-end visibility starts with pulling data from ERP, TMS, WMS, telematics, carrier feeds, and supplier systems into one view. Without that breadth, the tower sees a fraction of the network and misses the disruptions that matter.
Exception detection then filters that stream for events worth a human’s attention. A mature system adds context, so a two-hour delay on a shipment with three days of buffer does not trigger the same alert as a two-hour delay on a same-day order. Vendor guidance on the control tower technology value matrix states that mature towers must link disruptions to their downstream financial and operational consequences to be genuinely decision-ready.
Analytics and simulation let planners test trade-offs before committing: what happens to service levels if a supplier ships three days late, or if a lane is rerouted around a port closure. Prescriptive recommendations turn that analysis into a ranked list of options.
The capability that separates a modern tower from a reporting tool is orchestration, meaning the system can act on a recommendation rather than just surface it. Typical supported actions include:
- Rebooking a shipment onto an alternate carrier when a delay crosses a threshold
- Releasing a held order once a credit or inventory condition clears
- Reprioritizing a pick or ship sequence to protect a customer commitment
- Triggering a supplier alert with an automatically calculated impact estimate
Overlay vs Orchestration: Choosing the Right Starting Point
Vendors sell two very different things under the same “control tower” label, and confusing them is the single most common procurement mistake. An overlay sits on top of existing systems, pulls data for viewing, and deploys in weeks with a modest integration footprint. Orchestration goes further: it writes back into TMS, WMS, or ERP systems to execute actions, which means deeper integration, a longer timeline, and a larger budget line for connecting those systems.
Buyers frequently pay for orchestration-tier licensing and then only ever use the overlay features, because nobody scoped the write-back integrations at signing. The buyer’s guide from Supply Chain Research warns that scope ambiguity, meaning never defining what “control tower” means for your operation, makes vendor comparisons close to meaningless.
Picking the right starting scope comes down to a short sequence:
- Write down the specific business question the tower must answer, such as “which shipments will miss their delivery window this week.”
- Decide whether the answer requires a person to act on the alert or the system to act automatically.
- If a person acts, an overlay is enough for a first phase.
- If the system must act, budget for orchestration-level integration work from day one, not as a phase-two surprise.
Agentic AI and Automation: Power and Guardrails
Agentic AI refers to software agents that detect a problem and carry out a corrective action themselves, inside guardrails a human has set, rather than stopping at a recommendation. That is a meaningfully different capability from predictive analytics, which forecasts an outcome, or prescriptive analytics, which ranks options for a person to choose. The Supply Chain Research buyer’s guide frames this recommend-to-act shift as the defining change in control tower technology for 2026.
In practice, safe agentic use cases tend to be repeatable and reversible:
- Automatically rerouting a shipment to a pre-approved alternate carrier
- Reprioritizing a warehouse pick queue when a high-priority order is at risk
- Releasing a routine order once a standard condition, like payment clearance, is met
- Flagging and pausing (rather than canceling) an order that fails a data quality check
Anything with irreversible financial or safety consequences, such as canceling a purchase order or committing new capacity, should route to a human for approval rather than executing automatically. Governance is not optional at this stage: explainability (why the agent chose this action), confidence thresholds, approval gates for higher-risk actions, and audit logs that record every autonomous decision. The same guide recommends designing gating criteria that define confidence thresholds, step-down approval paths, and rollback procedures before any agent goes live.
Pro Tip: Pilot agentic features on one low-risk, high-frequency workflow, such as carrier reassignment, and measure the outcome for 60 to 90 days before expanding the agent’s authority.
Architecture and Data Readiness: The Unified Data Layer
None of the capabilities above work without a foundation most projects underestimate: a unified data layer that normalizes information from every source system into one consistent structure. Practitioner reporting on the system of action identifies the lack of this layer as the single biggest technical barrier, since without it a control tower inherits every source system’s data quality problems and latency delays.
Getting the data layer right involves a few consistent patterns:
- APIs and event streams for near-real-time feeds like telematics and carrier tracking
- EDI for the batch transactions still common with legacy supplier and carrier systems
- Master data management so a shipment, SKU, or location means the same thing across every connected system
- Enrichment steps that fill gaps, such as attaching lead time or cost data to a raw tracking event
Latency matters as much as connectivity: a feed that updates once a day cannot support same-day exception detection, no matter how good the analytics layer is on top of it.
Before signing anything, insist on seeing these things in a live demo rather than a canned one: a connector pulling your own sample data, a reconciliation report showing how the system handles mismatched records, and the error-handling behavior when a feed drops or sends malformed data. A vendor that cannot show this on request is asking you to buy the data layer on faith.
A Practical Roadmap and the KPIs That Prove Value
A phased rollout keeps risk and spend proportional to what the project has actually proven, rather than betting the full budget on an unproven agent.
- Phase 0, scoping: define the specific business questions the tower must answer and who acts on each answer.
- Phase 1, visibility pilot (20 to 60 days): connect the highest-value data sources, stand up the dashboard, and establish baseline metrics before automating anything.
- Phase 2, prescriptive integration (60 to 180 days): layer in recommendation logic and simulation, still with a human making the final call.
- Phase 3, governed agentic actions (past 180 days): enable autonomous execution on the narrow set of workflows proven safe in Phase 2, with full audit logging.
Track decision velocity (time from detection to resolution), expedite spend, on-time-in-full rate, open exception count, and manual hours spent on exception handling at each phase, comparing every number back to the Phase 1 baseline.
Nucleus Research’s 2026 Value Matrix found that vendors connecting visibility, planning, execution, and decision intelligence deliver higher returns by shortening the detection-to-resolution cycle, the same cycle these phased KPIs are designed to measure.
A 90-Day Pilot Example and What It Delivers
An AI Readiness Audit typically starts by mapping an operation’s existing systems and manual workflows to find where automation removes the most friction, rather than proposing a generic platform swap. That audit typically feeds directly into a 90-day control tower pilot scoped to one measurable business question.
A typical 90-day scope includes connecting several priority data sources rather than the entire system landscape.
- Standing up a dashboard against the KPIs defined in Phase 1 of the roadmap above
- Automating one narrow, low-risk agentic workflow, such as a scheduling or carrier reassignment task
- A measurement plan comparing baseline metrics against the pilot’s end-of-period numbers
The goal of a pilot this scoped is a decision, not a platform: proof the approach reduces decision latency and exception volume in real-time logistics analytics before any larger commitment gets made. Governance, including approval thresholds and handoff points back to human planners, gets built into the pilot from day one rather than bolted on afterward.
Where AI Control Towers Are Heading Next
Agentic AI is the headline trend for 2026, but it is not the only direction control tower technology is moving. Multi-agent coordination, where several specialized agents handle different parts of a disruption (one agent assessing inventory impact, another negotiating a carrier swap) and then reconcile their recommendations, is starting to appear in more mature deployments rather than a single monolithic decision engine.
Deeper integration with supplier-side and carrier-side systems is also extending the tower’s field of view further upstream, so disruptions get caught before they reach the reader’s own network rather than after. That depends entirely on the same unified data layer discussed earlier, extended to partners rather than just internal systems.
Explainability tooling is maturing alongside the agents themselves, giving planners a plain-language trace of why an agent chose a particular action rather than a black-box confidence score. That matters directly for the audit and governance requirements already built into agentic pilots, and it is likely to become a baseline expectation rather than a differentiator as more towers add autonomous actions.
Simulation is also getting cheaper to run, which means scenario testing that once required a dedicated planning cycle can increasingly run on demand against live data, closing the loop between “what if” analysis and same-day decision making.
None of these directions replace the fundamentals covered above. A tower without a unified data layer or clear governance will not benefit from multi-agent coordination any more than it benefits from a single agent today; the foundation still has to come first.
What Pilots Have Shown in Practice
Documented field reports describe a consistent pattern: pilots that focus on one high-value workflow, such as correcting shipment schedules or reassigning carriers when a delay is detected, tend to produce a measurable result within 60 to 90 days when data connectivity and executive sponsorship are already in place. The pattern holds regardless of the specific vendor or industry involved, because the constraint is almost always organizational readiness rather than the software itself.
The common thread across these pilots is narrowness. Teams that try to automate an entire network’s decision-making in one phase rarely finish on schedule, while teams that pick one workflow, such as automating a single exception-handling task, tend to have a clean before-and-after comparison to show leadership by the end of the pilot window.
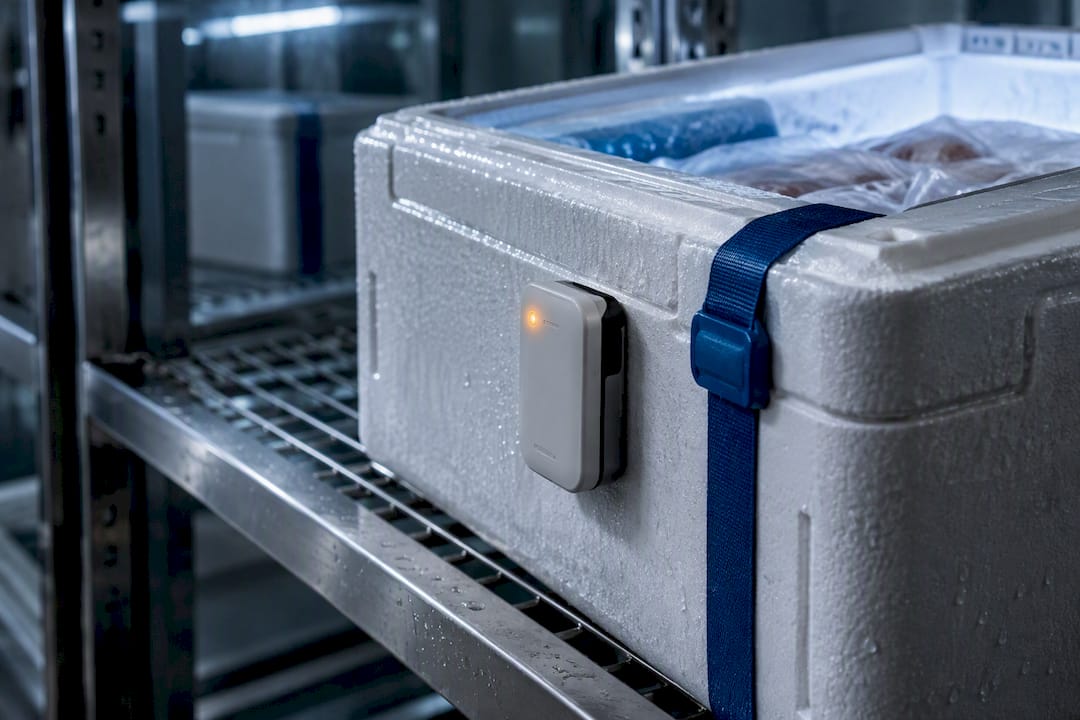
A cold chain monitoring pilot illustrates the same pattern applied to a specialized use case: temperature and location data feed a dashboard, exceptions trigger an alert, and audit controls track every automated decision so the pilot’s outcome is fully traceable once the review period ends. The specifics change by industry, but the shape of a successful pilot does not: one workflow, a clear baseline, and a defined measurement window.
Where These Projects Run Into Trouble
The most consistent risk in control tower deployments is treating data integration as an afterthought rather than the project’s primary deliverable. Nucleus Research’s market commentary identifies data integration as the decisive cost driver in most deployments, meaning teams that budget for software licensing but not for the integration work behind it consistently run over both budget and timeline.
A second risk is enabling autonomous actions before governance controls are actually tested, not just documented. An agent that can reroute a shipment without a tested rollback procedure is a liability the moment it makes one bad call at scale, which is why the phased approach in the implementation roadmap holds agentic actions until Phase 3.
Alert fatigue is a quieter but equally damaging risk: a tower that flags every minor delay with the same urgency as a critical one trains planners to ignore its alerts entirely within weeks, which defeats the exception detection layer’s entire purpose.
Finally, organizational resistance shows up when frontline planners were not involved in defining what “good” looks like for the tower’s recommendations. A system that technically works but does not match how planners actually make decisions gets quietly worked around rather than adopted.
How to Evaluate a Control Tower Before You Buy
Start every evaluation with the scope question from earlier: write down the specific business question the tower must answer, and hold every vendor demo to that standard rather than a generic feature tour. A vendor that cannot address your specific scenario with your own sample data is showing you a demo, not a fit assessment.
During the demo itself, ask to see a live connector pulling data from one of your actual source systems, not a pre-loaded sample dataset, along with a reconciliation report showing how mismatched or duplicate records get handled. Ask what happens when a feed drops entirely: does the system flag the gap, or does it silently show stale data as current.
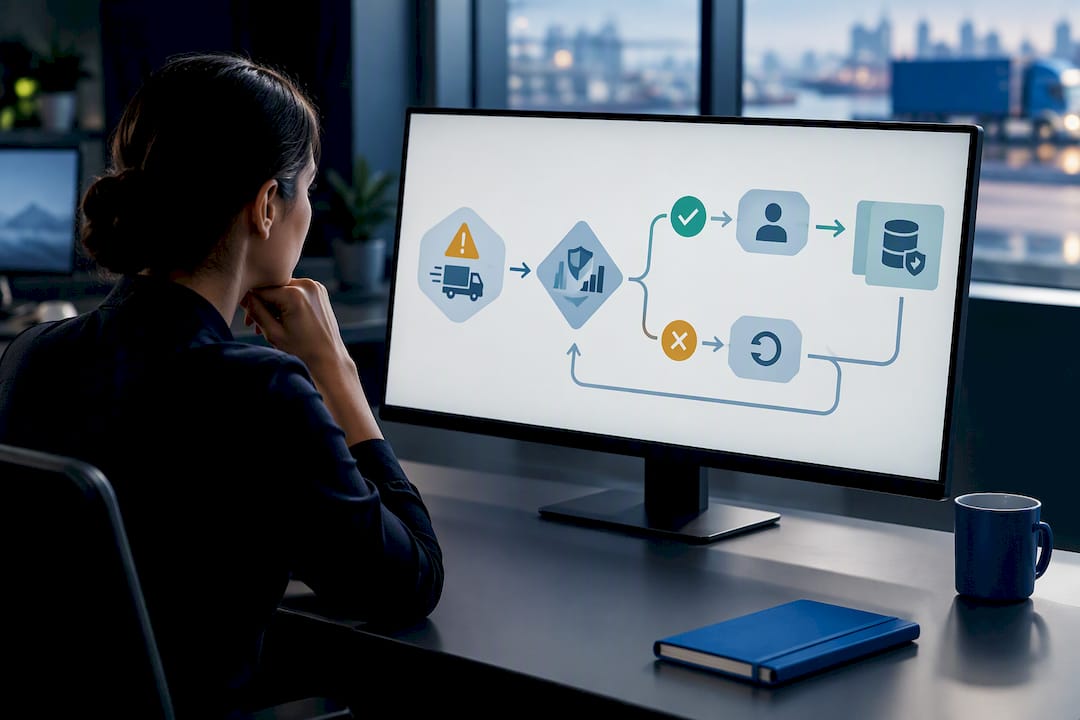
On governance, ask for a concrete walk-through of one autonomous action from detection to execution, including the confidence threshold that triggered it, the approval path if the confidence score had been lower, and where that decision shows up in an audit log. A vendor without a clear answer to that sequence is not ready for the agentic tier they may be selling you.
Finally, separate the overlay-tier and orchestration-tier pricing explicitly, and confirm in writing which write-back integrations are included at each tier, since this is exactly where the procurement mistake described earlier tends to happen.
Common Use Cases Across Logistics Operations
AI control towers show up differently depending on the operation, but the underlying pattern of visibility, detection, and action repeats across each one.
In freight and transportation, the most common application is exception management: detecting late shipments, reassigning carriers, and recalculating estimated arrival times as conditions change. In warehousing and distribution, towers reprioritize pick and ship sequences when a high-priority order is at risk of missing its window.
Manufacturing supply chains use control towers to link supplier delays to downstream production impact, so a raw material shortage triggers a production schedule adjustment rather than a surprise on the shop floor. Retail and e-commerce operations lean on the same detection layer to manage inventory allocation across fulfillment centers when demand spikes unexpectedly in one region.
Cold chain and temperature-sensitive logistics represent a more specialized case, where the tower’s exception detection has to account for time-sensitive spoilage risk rather than just delivery delay, feeding directly into the kind of audit-controlled pilot described earlier in this article.
Balancing Ambition, Risk, and Speed When Automating Decisions
Most control tower projects fail not because the AI underperforms, but because nobody defined the business question before shopping for a platform. Define what decision you need to make faster, then evaluate vendors against that, not against a feature checklist.
Integration work takes longer than sales conversations suggest, almost always. Budget for it explicitly rather than treating it as a rounding error on top of the licensing fee.
Measure a small, narrow pilot before scaling any automation. A single well-instrumented workflow tells you more about whether agentic AI fits your operation than any vendor’s roadmap slide ever will.
— Souhail
Getting From Visibility to Action in 90 Days
An AI Readiness Audit maps existing systems and workflows to identify exactly where an AI control tower would remove the most friction, rather than starting from a generic platform recommendation. From there, a focused 90-day pilot connects priority data sources, builds a working dashboard, and automates one measurable workflow so real numbers, not projections, inform decisions before committing to a larger rollout.
What you can reasonably expect from that 90-day window:
- A scoped pilot covering two to four connected data sources rather than a full system overhaul
- One agentic workflow live and measured against a baseline you set on day one
- A clear governance framework covering approval thresholds and audit logging before any action goes autonomous
- A documented outcome you can use to decide whether to scale, adjust, or stop
If you want a practical next step rather than another vendor comparison, start with the AI Readiness Audit and scope your own 90-day pilot.
Sources
- Nucleus Research Releases 2026 Control Tower Technology Value Matrix
- Supply Chain Control Towers | Supply Chain Research
- Control tower technology value matrix (Blue Yonder PDF)
- The system of action runs on a unified data layer
FAQ
What Is a Control Tower in Logistics?
A control tower in logistics is a centralized system that aggregates data from carriers, warehouses, and suppliers to give planners one view of shipments and inventory across a network. Its core job is spotting problems, such as delays or shortages, before they cause a bigger disruption downstream.
What Is an AI Control Tower?
An AI control tower adds machine learning and, increasingly, agentic AI on top of that centralized visibility, so the system detects exceptions, recommends fixes, and in more mature deployments executes low-risk corrective actions itself. The 2026 shift toward agentic AI moves these systems from recommending a response to acting on it within human guardrails.
Is AI Being Used in Logistics?
Yes, AI is used across logistics operations for demand forecasting, exception detection, route optimization, and increasingly for autonomous actions like carrier rerouting inside a control tower. Adoption tends to start with visibility and prescriptive recommendations before organizations extend it into governed autonomous execution.
What Is the Purpose of a Control Tower?
A control tower’s purpose is to shorten the time between spotting a disruption and resolving it, which reduces expedite costs, inventory exposure, and the manual hours spent chasing down exceptions by hand. The Nucleus Research Value Matrix ties that faster detection-to-resolution cycle directly to higher returns on the technology.